 Midjourney
Back to Blog kubernetes
 devchallenge
 ai
 ai
 claude
 devchallenge
 gemini
Multi-tier model routing on GKE: balancing Gemini 4 Argon reasoning depth with latency and cost
Olivier Bourgeois October 19, 2026
0 views
Build a high-throughput model routing gateway on GKE to dynamically route requests between Gemini 4 Argon, Gemini 3.8 Flash, and local Gemma 4 models.
title: "Multi-tier model routing on GKE: balancing Gemini 4 Argon reasoning depth with latency and cost" published: true description: "Build a high-throughput model routing gateway on GKE to dynamically route requests between Gemini 4 Argon, Gemini 3.8 Flash, and local Gemma 4 models." tags: kubernetes, ai, gke, googlecloud cover_image: https://dev-to-uploads.s3.us-east-2.amazonaws.com/uploads/articles/dm5uqv0deix42cb2vlp2.png
Routing every incoming user prompt to a frontier reasoning model is the fastest way to blow through your token budget and degrade p99 tail latency. With the release of Gemini 4 Argon on the Gemini platform, engineering teams have access to deep multi-step reasoning in gemini-4-argon alongside high-throughput, low-latency execution in gemini-3.8-flash and open-weights models running directly on cluster accelerators.
In most production applications, workload complexity follows a steep power law. Roughly 70% of requests involve classification, summarization, schema extraction, or straightforward retrieval that a fast tier handles in a few hundred milliseconds. The remaining 30% require multi-hop synthesis, complex code generation, or ambiguous constraint solving where gemini-4-argon shines. Hardcoding a single model identifier in your application containers forces you to either overpay on simple queries or under-deliver on complex ones.
By building a centralized AI routing layer on Google Kubernetes Engine (GKE) using the GKE Gateway API, platform teams can classify prompt complexity at the ingress edge, route requests across Gemini tiers (gemini-4-argon and gemini-3.8-flash) and self-hosted GKE Inference Gateway pools, and enforce automatic fallback when rate limits occur.
In this article, I will break down the architecture of a multi-tier Gemini 4 Argon router on GKE, configure GKE Standard and Autopilot infrastructure with Workload Identity Federation for GKE, and walk through the routing, health-check, and observability configurations.
Why static model bindings fail in production
When application teams integrate directly with LLM endpoints inside dozens of individual microservices, three operational problems surface quickly:
- Unbounded token spend and latency inflation: A microservice calling
gemini-4-argonfor routine JSON formatting pays frontier token pricing and waits for deep reasoning chains whengemini-3.8-flashwould produce an identical schema in a fraction of the time. - Scattered credential and quota management: Managing Gemini platform API quotas, retry backoffs, and regional failover across 30 separate application repositories leads to inconsistent behavior during traffic spikes.
- No path to hybrid in-cluster offload: When high-volume, low-complexity tasks could be served at fixed cost by an open-weights model running on GKE GPU or TPU node pools, application code tightly coupled to a single model string cannot shift traffic without code changes and redeployments.
Centralizing model routing behind a GKE Gateway and an intelligent router service decouples client microservices from the underlying model tier.
Multi-tier routing architecture on GKE
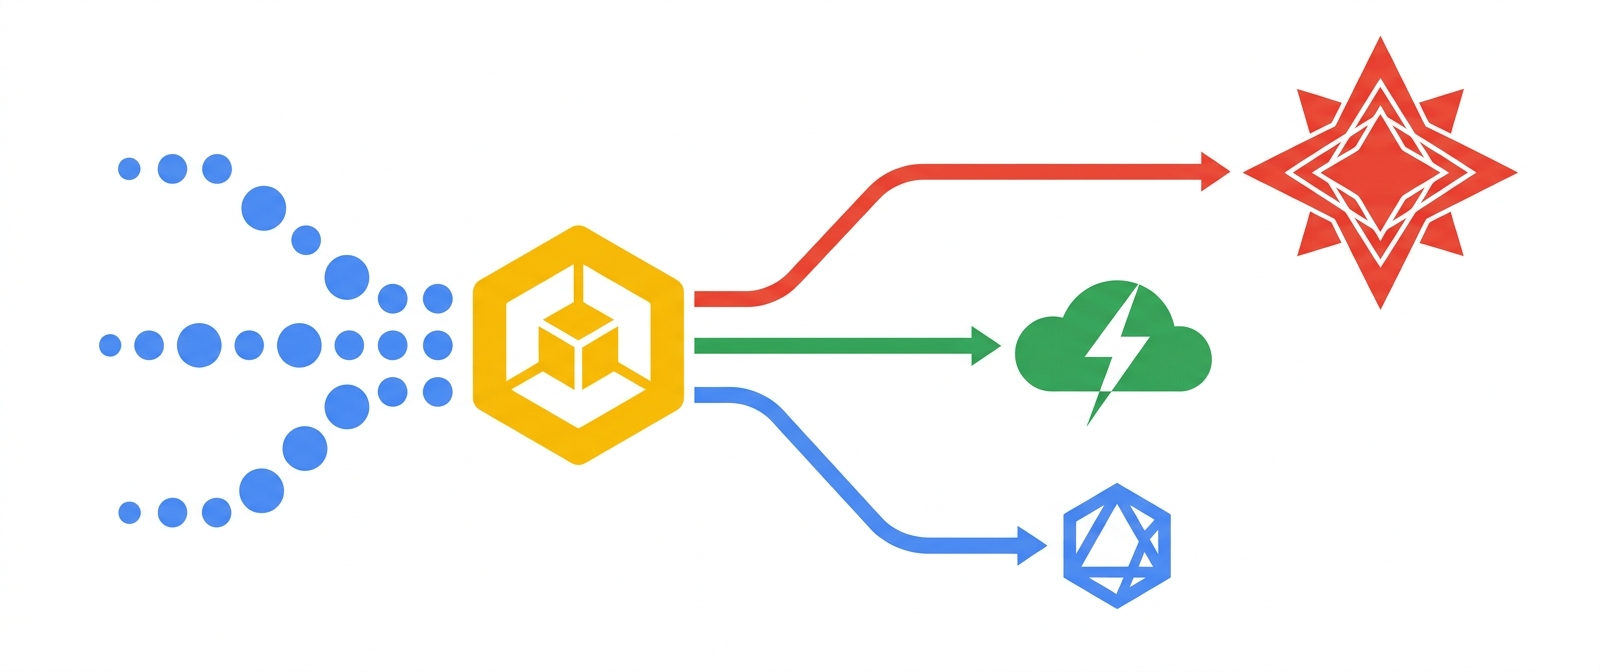
In this architecture, internal microservices send standard requests to a regional internal GKE Gateway (gke-l7-rilb). The Gateway forwards traffic to an ai-model-router service that evaluates request metadata or runs a fast complexity check before dispatching the request to one of three model tiers:
- Tier 1 (Frontier reasoning): High-complexity tasks, code synthesis, and multi-step planning route to
gemini-4-argonon the Gemini platform. - Tier 2 (Low-latency interactive): Routine summarization, classification, and structured extraction route to
gemini-3.8-flashon the Gemini platform. - Tier 3 (High-throughput local): High-volume batch transformations and strict data locality workloads route to an in-cluster vLLM pool running Gemma 4 via GKE Inference Gateway.
Here is how the three tiers compare across production operating dimensions:
| Routing tier | Target model | Primary workload profile | Fallback path on 429 / timeout |
|---|---|---|---|
| Tier 1: Frontier reasoning | gemini-4-argon (Gemini platform) | Multi-step planning, complex code synthesis, ambiguous root-cause analysis | us multi-region endpoint, then graceful downgrade to gemini-3.8-flash |
| Tier 2: Low-latency interactive | gemini-3.8-flash (Gemini platform) | Real-time chat, structured extraction, classification, single-turn tool calls | us multi-region endpoint, then in-cluster open-weights pool |
| Tier 3: High-throughput local | Open-weights (Gemma 4 via vLLM on GKE) | High-volume entity tagging, PII scrubbing, fixed-cost background jobs | Burst overflow to gemini-3.8-flash on the Gemini platform |
The sample router later in this article implements the Tier 1 and Tier 2 location failover and the Tier 1 downgrade. The paths into and out of the in-cluster Tier 3 pool depend on your Inference Gateway setup and are left to your own dispatch logic.
Configuring Workload Identity and GKE compute
To call the Gemini platform without distributing static service account keys, bind the ai-model-router Kubernetes ServiceAccount directly to an IAM role using Workload Identity Federation for GKE. This works identically across GKE Standard and GKE Autopilot clusters running GKE 1.32 or later with the GKE Gateway controller enabled (--gateway-api=standard) and an active regional proxy-only subnet (--purpose=REGIONAL_MANAGED_PROXY) in your VPC.
Note on model identifiers and locations: The examples below use
gemini-4-argon(Gemini 4 Argon) andgemini-3.8-flash(Gemini 3.8 Flash) configured via environment variables (PRO_MODELandFLASH_MODEL). Both models are served from theglobalendpoint and theusandeumulti-region endpoints, not from individual regions such asus-central1, so the router fails over fromglobaltous.
export PROJECT_ID="production-ai-platform"
export PROJECT_NUMBER=$(gcloud projects describe "${PROJECT_ID}" --format="value(projectNumber)")
export LOCATION="us-central1"
export CLUSTER_NAME="ai-gateway-cluster"

# Point kubectl at the cluster
gcloud container clusters get-credentials "${CLUSTER_NAME}" --location="${LOCATION}" --project="${PROJECT_ID}"

# Create the namespace and Kubernetes ServiceAccount
kubectl create namespace ai-routing
kubectl create serviceaccount gemini-router-sa --namespace=ai-routing

# Grant the Kubernetes ServiceAccount permission to invoke Gemini platform models
# (the underlying IAM role string is still roles/aiplatform.user)
gcloud projects add-iam-policy-binding "${PROJECT_ID}" \
    --member="principal://iam.googleapis.com/projects/${PROJECT_NUMBER}/locations/global/workloadIdentityPools/${PROJECT_ID}.svc.id.goog/subject/ns/ai-routing/sa/gemini-router-sa" \
    --role="roles/aiplatform.user" \
    --condition=None
Provisioning capacity on GKE Autopilot vs. Standard
For the router Deployment itself, standard CPU compute is sufficient. If you also operate Tier 3 (in-cluster open-weights inference via GKE Inference Gateway for high-volume offload), configure your accelerator capacity according to your cluster mode:
- GKE Autopilot with
ComputeClass: Define a declarativeComputeClass(cloud.google.com/v1) that requests NVIDIA L4 GPUs (gpu.type: nvidia-l4,gpu.count: 2) with prioritized fallback from on-demand capacity to Spot VMs during regional stockouts. - GKE Standard node pools: Create a dedicated GPU node pool (
gcloud container node-pools create vllm-l4-pool --cluster="${CLUSTER_NAME}" --location="${LOCATION}" --machine-type=g2-standard-24 --accelerator=type=nvidia-l4,count=2,gpu-driver-version=latest --enable-autoscaling --min-nodes=1 --max-nodes=6).
Implementing the Gemini 4 tier router
The ai-model-router service inspects incoming requests, estimates task complexity (using explicit client headers, token count thresholds, or keyword triggers), and dispatches the call through the google-genai SDK with cross-location failover and cross-tier fallback. It also exposes a /healthz endpoint that both the Pod readinessProbe and the GKE Gateway load balancer health check use to verify backend readiness.
Save the following implementation as router_app.py:
import os
import time
from fastapi import FastAPI, Header, HTTPException
from pydantic import BaseModel
from google import genai
from google.genai import types
from google.genai.errors import APIError

app = FastAPI(title="GKE Gemini 4 Argon Multi-Tier Router")

PROJECT_ID = os.environ["GOOGLE_CLOUD_PROJECT"]
PRIMARY_LOCATION = os.environ.get("PRIMARY_LOCATION", "global")
SECONDARY_LOCATION = os.environ.get("SECONDARY_LOCATION", "us")
PRO_MODEL = os.environ.get("PRO_MODEL", "gemini-4-argon")
FLASH_MODEL = os.environ.get("FLASH_MODEL", "gemini-3.8-flash")

# Project-scoped Gemini platform clients authenticated through Workload Identity Federation for GKE.
# The vertexai=True flag is the SDK switch for project-scoped IAM auth instead of an API key.
primary_client = genai.Client(vertexai=True, project=PROJECT_ID, location=PRIMARY_LOCATION)
secondary_client = genai.Client(vertexai=True, project=PROJECT_ID, location=SECONDARY_LOCATION)

REASONING_KEYWORDS = {"architect", "debug", "prove", "multi-step", "optimize", "trade-off", "root cause"}


class PromptRequest(BaseModel):
    prompt: str
    system_instruction: str | None = None
    require_deep_reasoning: bool = False


def select_model_tier(req: PromptRequest, routing_hint: str | None) -> str:
    """Selects the Gemini 4 Argon (frontier) or Gemini 3.8 Flash tier based on client hints and prompt characteristics."""
    if routing_hint == "pro" or req.require_deep_reasoning:
        return PRO_MODEL
    if routing_hint == "flash":
        return FLASH_MODEL

    prompt_lower = req.prompt.lower()
    word_count = len(req.prompt.split())
    has_reasoning_trigger = any(kw in prompt_lower for kw in REASONING_KEYWORDS)

    if word_count > 600 or has_reasoning_trigger:
        return PRO_MODEL
    return FLASH_MODEL


def build_config(model: str, system_instruction: str | None) -> types.GenerateContentConfig:
    """Gemini 4 Argon ignores sampling parameters and defaults to the MEDIUM thinking level,
    so temperature is only set on the Flash tier."""
    if model == PRO_MODEL:
        return types.GenerateContentConfig(system_instruction=system_instruction)
    return types.GenerateContentConfig(system_instruction=system_instruction, temperature=0.2)


@app.get("/healthz")
def health_check():
    return {"status": "ok"}


@app.post("/v1/generate")
def generate_response(
    req: PromptRequest,
    x_model_tier: str | None = Header(default=None),
):
    target_model = select_model_tier(req, x_model_tier)
    start_time = time.monotonic()

    # Attempt the global endpoint, then the us multi-region endpoint, then downgrade to Flash
    # unless the caller explicitly required deep reasoning
    attempt_chain = [
        (primary_client, PRIMARY_LOCATION, target_model),
        (secondary_client, SECONDARY_LOCATION, target_model),
    ]
    explicit_pro = x_model_tier == "pro" or req.require_deep_reasoning
    if target_model == PRO_MODEL and not explicit_pro:
        attempt_chain.append((primary_client, PRIMARY_LOCATION, FLASH_MODEL))

    for attempt_client, location, candidate_model in attempt_chain:
        try:
            response = attempt_client.models.generate_content(
                model=candidate_model,
                contents=req.prompt,
                config=build_config(candidate_model, req.system_instruction),
            )
            latency_ms = round((time.monotonic() - start_time) * 1000, 2)
            usage = response.usage_metadata
            return {
                "model_used": candidate_model,
                "location": location,
                "fallback_triggered": (location != PRIMARY_LOCATION or candidate_model != target_model),
                "latency_ms": latency_ms,
                "usage": {
                    "prompt_tokens": (usage.prompt_token_count or 0) if usage else 0,
                    "output_tokens": (usage.candidates_token_count or 0) if usage else 0,
                    "thoughts_tokens": (usage.thoughts_token_count or 0) if usage else 0,
                },
                "output": response.text,
            }
        except APIError as exc:
            if exc.code in (429, 500, 503, 504):
                continue
            raise HTTPException(status_code=exc.code or 500, detail=str(exc))

    raise HTTPException(status_code=503, detail="All Gemini endpoints exhausted")
Exposing the router via GKE Gateway API and GCPBackendPolicy
Because gemini-4-argon reasoning chains on large contexts can take 30 to 90 seconds to complete, standard 30-second HTTP load balancer timeouts will prematurely drop connections and cause clients to retry expensive requests.
Configure a GKE Gateway, HTTPRoute, and GCPBackendPolicy (networking.gke.io/v1) to extend the backend timeout to 180 seconds and enable connection draining during rolling updates. Unlike GKE Ingress, GKE Gateway does not infer load balancer health checks from the Pod readinessProbe; it probes / by default, which the router answers with a 404. Add a HealthCheckPolicy (networking.gke.io/v1) that points the load balancer at /healthz:
apiVersion: apps/v1
kind: Deployment
metadata:
  name: ai-model-router
  namespace: ai-routing
spec:
  replicas: 3
  selector:
    matchLabels:
      app: ai-model-router
  template:
    metadata:
      labels:
        app: ai-model-router
    spec:
      serviceAccountName: gemini-router-sa
      containers:
      - name: router
        image: us-central1-docker.pkg.dev/production-ai-platform/ai-routing/gemini-4-router:v1.0.0
        ports:
        - containerPort: 8080
        env:
        - name: GOOGLE_CLOUD_PROJECT
          value: "production-ai-platform"
        - name: PRIMARY_LOCATION
          value: "global"
        - name: SECONDARY_LOCATION
          value: "us"
        - name: PRO_MODEL
          value: "gemini-4-argon"
        - name: FLASH_MODEL
          value: "gemini-3.8-flash"
        readinessProbe:
          httpGet:
            path: /healthz
            port: 8080
          initialDelaySeconds: 5
          periodSeconds: 10
        resources:
          requests:
            cpu: "500m"
            memory: "512Mi"
---
apiVersion: v1
kind: Service
metadata:
  name: ai-model-router-svc
  namespace: ai-routing
spec:
  selector:
    app: ai-model-router
  ports:
  - port: 80
    targetPort: 8080
---
apiVersion: networking.gke.io/v1
kind: GCPBackendPolicy
metadata:
  name: gemini-router-backend-policy
  namespace: ai-routing
spec:
  default:
    timeoutSec: 180
    connectionDraining:
      drainingTimeoutSec: 60
  targetRef:
    group: ""
    kind: Service
    name: ai-model-router-svc
---
apiVersion: networking.gke.io/v1
kind: HealthCheckPolicy
metadata:
  name: gemini-router-healthcheck
  namespace: ai-routing
spec:
  default:
    checkIntervalSec: 10
    timeoutSec: 5
    healthyThreshold: 1
    unhealthyThreshold: 3
    config:
      type: HTTP
      httpHealthCheck:
        port: 8080
        requestPath: /healthz
  targetRef:
    group: ""
    kind: Service
    name: ai-model-router-svc
---
apiVersion: gateway.networking.k8s.io/v1
kind: Gateway
metadata:
  name: internal-ai-gateway
  namespace: ai-routing
spec:
  gatewayClassName: gke-l7-rilb
  listeners:
  - name: http
    protocol: HTTP
    port: 80
---
apiVersion: gateway.networking.k8s.io/v1
kind: HTTPRoute
metadata:
  name: gemini-routing-route
  namespace: ai-routing
spec:
  parentRefs:
  - name: internal-ai-gateway
  rules:
  - matches:
    - path:
        type: PathPrefix
        value: /v1/generate
    backendRefs:
    - name: ai-model-router-svc
      port: 80
If you also run an in-cluster vLLM pool managed by GKE Inference Gateway (InferencePool in inference.networking.k8s.io/v1 and InferenceObjective in inference.networking.x-k8s.io for workload prioritization), you can attach an additional HTTPRoute rule on the same internal-ai-gateway (or dispatch internally from router_app.py) to route high-volume batch traffic directly to group: inference.networking.k8s.io, kind: InferencePool.
Verifying the Gateway and routing behavior
After applying the manifests, verify that the GKE Gateway controller has programmed the internal load balancer and attached both backend policies:
# Confirm Gateway programmed status and internal IP address
kubectl get gateway internal-ai-gateway -n ai-routing

# Verify that both policies are attached to the Service (look for Reason: Attached)
kubectl describe gcpbackendpolicy gemini-router-backend-policy -n ai-routing
kubectl describe healthcheckpolicy gemini-router-healthcheck -n ai-routing
Because gke-l7-rilb exposes only an internal IP address, look up the address with kubectl, then send the test requests from a client in the same VPC and region (for example, a debug Pod in the cluster):
export GATEWAY_IP=$(kubectl get gateway internal-ai-gateway -n ai-routing -o jsonpath='{.status.addresses[0].value}')

# 1. Fast classification query (routes automatically to gemini-3.8-flash)
curl -s -X POST "http://${GATEWAY_IP}/v1/generate" \
    -H "Content-Type: application/json" \
    -d '{"prompt": "Extract the HTTP status code from this log line: GET /checkout 502 Bad Gateway"}' | jq .

# 2. Complex architectural query (routes automatically to gemini-4-argon)
curl -s -X POST "http://${GATEWAY_IP}/v1/generate" \
    -H "Content-Type: application/json" \
    -d '{"prompt": "Analyze the root cause and trade-offs of etcd leader election timeouts during cross-zone network partitions."}' | jq .
Expected response showing the selected tier, location, fallback status, and token accounting (including reasoning thoughts_tokens):
{
  "model_used": "gemini-4-argon",
  "location": "global",
  "fallback_triggered": false,
  "latency_ms": 2840.15,
  "usage": {
    "prompt_tokens": 24,
    "output_tokens": 412,
    "thoughts_tokens": 186
  },
  "output": "..."
}
Operational caveats and when not to use a router
Before introducing a model router in front of Gemini 4 Argon, weigh these operational trade-offs:
- Classifier accuracy vs. quality regressions: Heuristic or embedding-based routers can misclassify terse prompts that actually require deep reasoning (for example, a short mathematical puzzle). Always expose an explicit override header (
X-Model-Tier: pro) so latency-tolerant or high-stakes workflows bypass heuristics completely. - Multi-turn conversation state: Switching model tiers mid-conversation can alter output formatting or tool-calling behavior. For stateful chat sessions, pin the model tier selected on the first turn or evaluate tier upgrades only when a tool execution fails.
- When not to use a routing layer: If you operate a single application with predictable prompt complexity and uniform latency targets, calling the Gemini platform directly from the application SDK with built-in retry policies avoids maintaining an extra hop in your cluster.
Next steps
Decoupling your microservices from hardcoded model strings lets you adopt Gemini 4 Argon where its reasoning capabilities matter most while keeping routine queries fast and cost-effective on gemini-3.8-flash or in-cluster accelerators.
To expand this architecture, review the GKE Gateway API documentation, explore the GKE Inference Gateway guide for routing to self-hosted open models, and check the Gemini platform model locations and quota documentation for multi-region availability and throughput configuration.
Comments
More Blog
View alldevchallengeCongrats to the Hacktoberfest Open-Source AI Challenge Week 2: Side Hustle Winners!
We're excited to announce the winners of the Hacktoberfest Open-Source AI Challenge Week 2: Side...
J
JemaiBuilding a Multimodal, Suggestion-Based AI Writing Coach with Gemini and Google Docs
When we use generative AI to proofread our daily writing—whether technical reports, business...
T
Tanaikeai926 Steps, Two Lobotomies, and Zero Nudges: Flight-Testing the Commitment Machine Across Gemini, Claude, and GPT-OSS
A 2026 Harvard study of 718 companies found that AI agents write 30% more code and close zero additional tickets because review times jump 49%. Here is what happened when I put my 1986 Commitment Machine into live production across Gemini, Claude, and GPT-OSS.
R
Randal L. SchwartzclaudeTwo ways to build with Claude models on Google Cloud!
Choose Claude Models on Google Cloud (Google managed) for in-boundary security, regional data...
J
Jen HarveydevchallengeCongrats to the Sanity Challenge Winners!
We are thrilled to announce the winners of the Sanity Challenge, our partnership with Sanity built...
J
JemgeminiBuilding a Multi-Agent Token Usage Widget in Under 500 KB
How we built a 483 KB zero-WebKit macOS Universal Binary and a single-file Ubuntu HUD with...
J
JimmyLiaoReady-made automations for this
Workflows from the Neura Market marketplace related to this Midjourney resource
- Dynamically Switch Between LLMs for AI Agents Using LangChain Coden8n · $14.99 · Related topic
- Automate Graphic Wallpaper Creation with Midjourney and Canvas APIsn8n · $9.99 · Related topic
- Automate Your Creative Process with Midjourney and GPT-4 Image APIn8n · $8.22 · Related topic
- Create Animated Stories Using GPT-4o-mini, Midjourney, Kling, and Creatomate APIn8n · $24.99 · Related topic