LangChain has open-sourced the internal agent it built to run its own paid advertising, publishing a technical blog post on September 13, 2026 that details how the system works, what it cost to run, and where the company got it wrong. The Paid Media Agent is a long-running agent that lives in Slack, combines ad-platform data with lead and pipeline data from the company's warehouse every Monday, and posts a summary plus a branded PDF for each platform explaining changes, reasons, and next steps.
The results LangChain reports are concrete. Paid media went from 0 to 20% of marketing pipeline in six months, cost per qualified lead fell 30% from June to August, and monthly spend rose about 60% over the same period. On LinkedIn, the largest social channel, CPL came in 40% lower than in January. LangChain also says it saved about $5K per month by bringing analysis and reporting in-house instead of using an agency.
The blog post is credited to Amal Irgashev, Danny Lambert, and Jan Gomez. It runs an estimated 19 min read and is framed as a build log rather than a product announcement, though the company is making the agent available as a starting point for other teams.
From Organic Growth to Five Paid Channels
For its first three years, LangChain's sales pipeline grew largely organically through open source, content, YouTube, community, and meetups. In January, the company launched a paid advertising program to reach new regions and enterprise decision makers, with a goal to scale from organic growth to five paid channels in six months.
The team behind that push was small. It faced two immediate problems: tracking campaigns, experiments, and performance data across channels, and a set of technical hurdles that made cross-platform comparison hard. Each ad platform has its own data schema, and campaign parameters do not map cleanly to outcomes like sales inquiries, signups, and content downloads. At the same time, LangChain's product release cadence accelerated, which increased campaign volume.
The agent was built to close that gap. Its stated job is to track product announcements, draft campaigns, add keywords, test variations, and surface proposed experiments for approval, with a continuous learning loop. The company describes the open-source release as a starting point: teams can connect accounts, give company context, and deploy to Slack in one command with Managed Deep Agents.
LangChain built the agent on its own stack. It used LangChain Deep Agents as the agent harness to avoid building core infrastructure from scratch. Deep Agents manages access to files, code execution, and working memory, and gives the model tools to plan, delegate to subagents, and manage context. Managed Deep Agents, the managed version, handles hosting, sandboxes, Slack integration, and schedules. The company says that abstraction let it focus on the agent's actual job rather than infrastructure.
LangSmith, which LangChain describes as its agent engineering platform for debugging, evaluating, and deploying agents, provides two pieces of the runtime: LangSmith Sandbox and LangSmith Deployment. Every run gets a LangSmith Sandbox, an isolated microVM with 32 GB disk and a shell. The sandbox is equipped with pandas and DuckDB for analysis, openpyxl for spreadsheets, and WeasyPrint and Jinja2 for report generation.
The blog post is explicit that different agents need different computers. A content generation agent's sandbox has a headless browser, ffmpeg, media tools, and the brand book. A finance agent might need openpyxl and DuckDB. The Paid Media Agent's sandbox is tuned to its own work.
The company's framing of the whole exercise is that the agent should be equipped like a new hire. That means giving it a workspace rather than a prompt: a sandbox with software installed, business context written down, and clear operating instructions. The post returns to that idea repeatedly, and it is the thread that connects the context design, the tool design, and the permission model described later.
Six Skills, a Nineteen-Page Wiki, and Five Context Layers
Context management is the part of the build LangChain spends the most time explaining. Business knowledge is stored in Markdown across six skills and a nineteen-page wiki. The software and business wiki are baked into a snapshot, which reduced average startup time by 10 seconds.
Context is split into five layers, ordered by how quickly each layer changes: system prompt, skills, wiki, live tools, and deterministic code.
The system prompt is deliberately short. It contains a one-sentence role description, three short sections covering how to operate, where numbers come from, and how to present results, and pointers to other resources. LangChain warns that the naive approach of putting all context in the system prompt leads to an overly long, expensive, stale prompt.
Skills are six folders of instructions that are progressively disclosed at runtime. The agent initially sees only a title and description for each skill, and loads the full instructions only when a task calls for them.
The wiki is nineteen pages explaining the funnel, campaign goals, data source ownership, and past decisions, including what was decided in July. It follows a pattern LangChain credits to a Karpathy note on LLM wikis and to the company's own Wiki Memory work.
Live tools are fetched at request time. The agent made 218 calls for spend, settings, and pipeline data in the runs described.
Deterministic code handles calculations, date windows, account matching, and hard safeguards. One example given is a rule preventing the agent from cutting the top pipeline driver after one bad week.
The hardest line to draw, according to the post, is between skills and wiki. LangChain's test is simple: a skill should "work at another company," whereas the wiki should not. Skills are reusable instructions that would apply to any advertiser. The wiki is company-specific knowledge about LangChain's funnel, its data sources, and its history.
The post also argues that the context window is often the bottleneck, not the model, and that many apparent reasoning failures are actually context failures. The recommended posture is to treat the prompt as a map, with knowledge living in structured files at predictable locations.
Two Agents, Five Weeks, and a Unification
LangChain originally built two agent graphs because the user experiences differed.
The weekly report agent was scheduled, artifact-heavy, built as a Deep Agent with a sandbox, a large model, and PDF generation. The Slack agent was a lightweight loop on a cheaper model, with Google Ads and warehouse tools, no sandbox, and read-only access.
The split lasted five weeks. Every new capability had to be implemented twice, and features reached Slack and the report at different times. Slack could not process attachments or answer follow-ups on Monday reports.
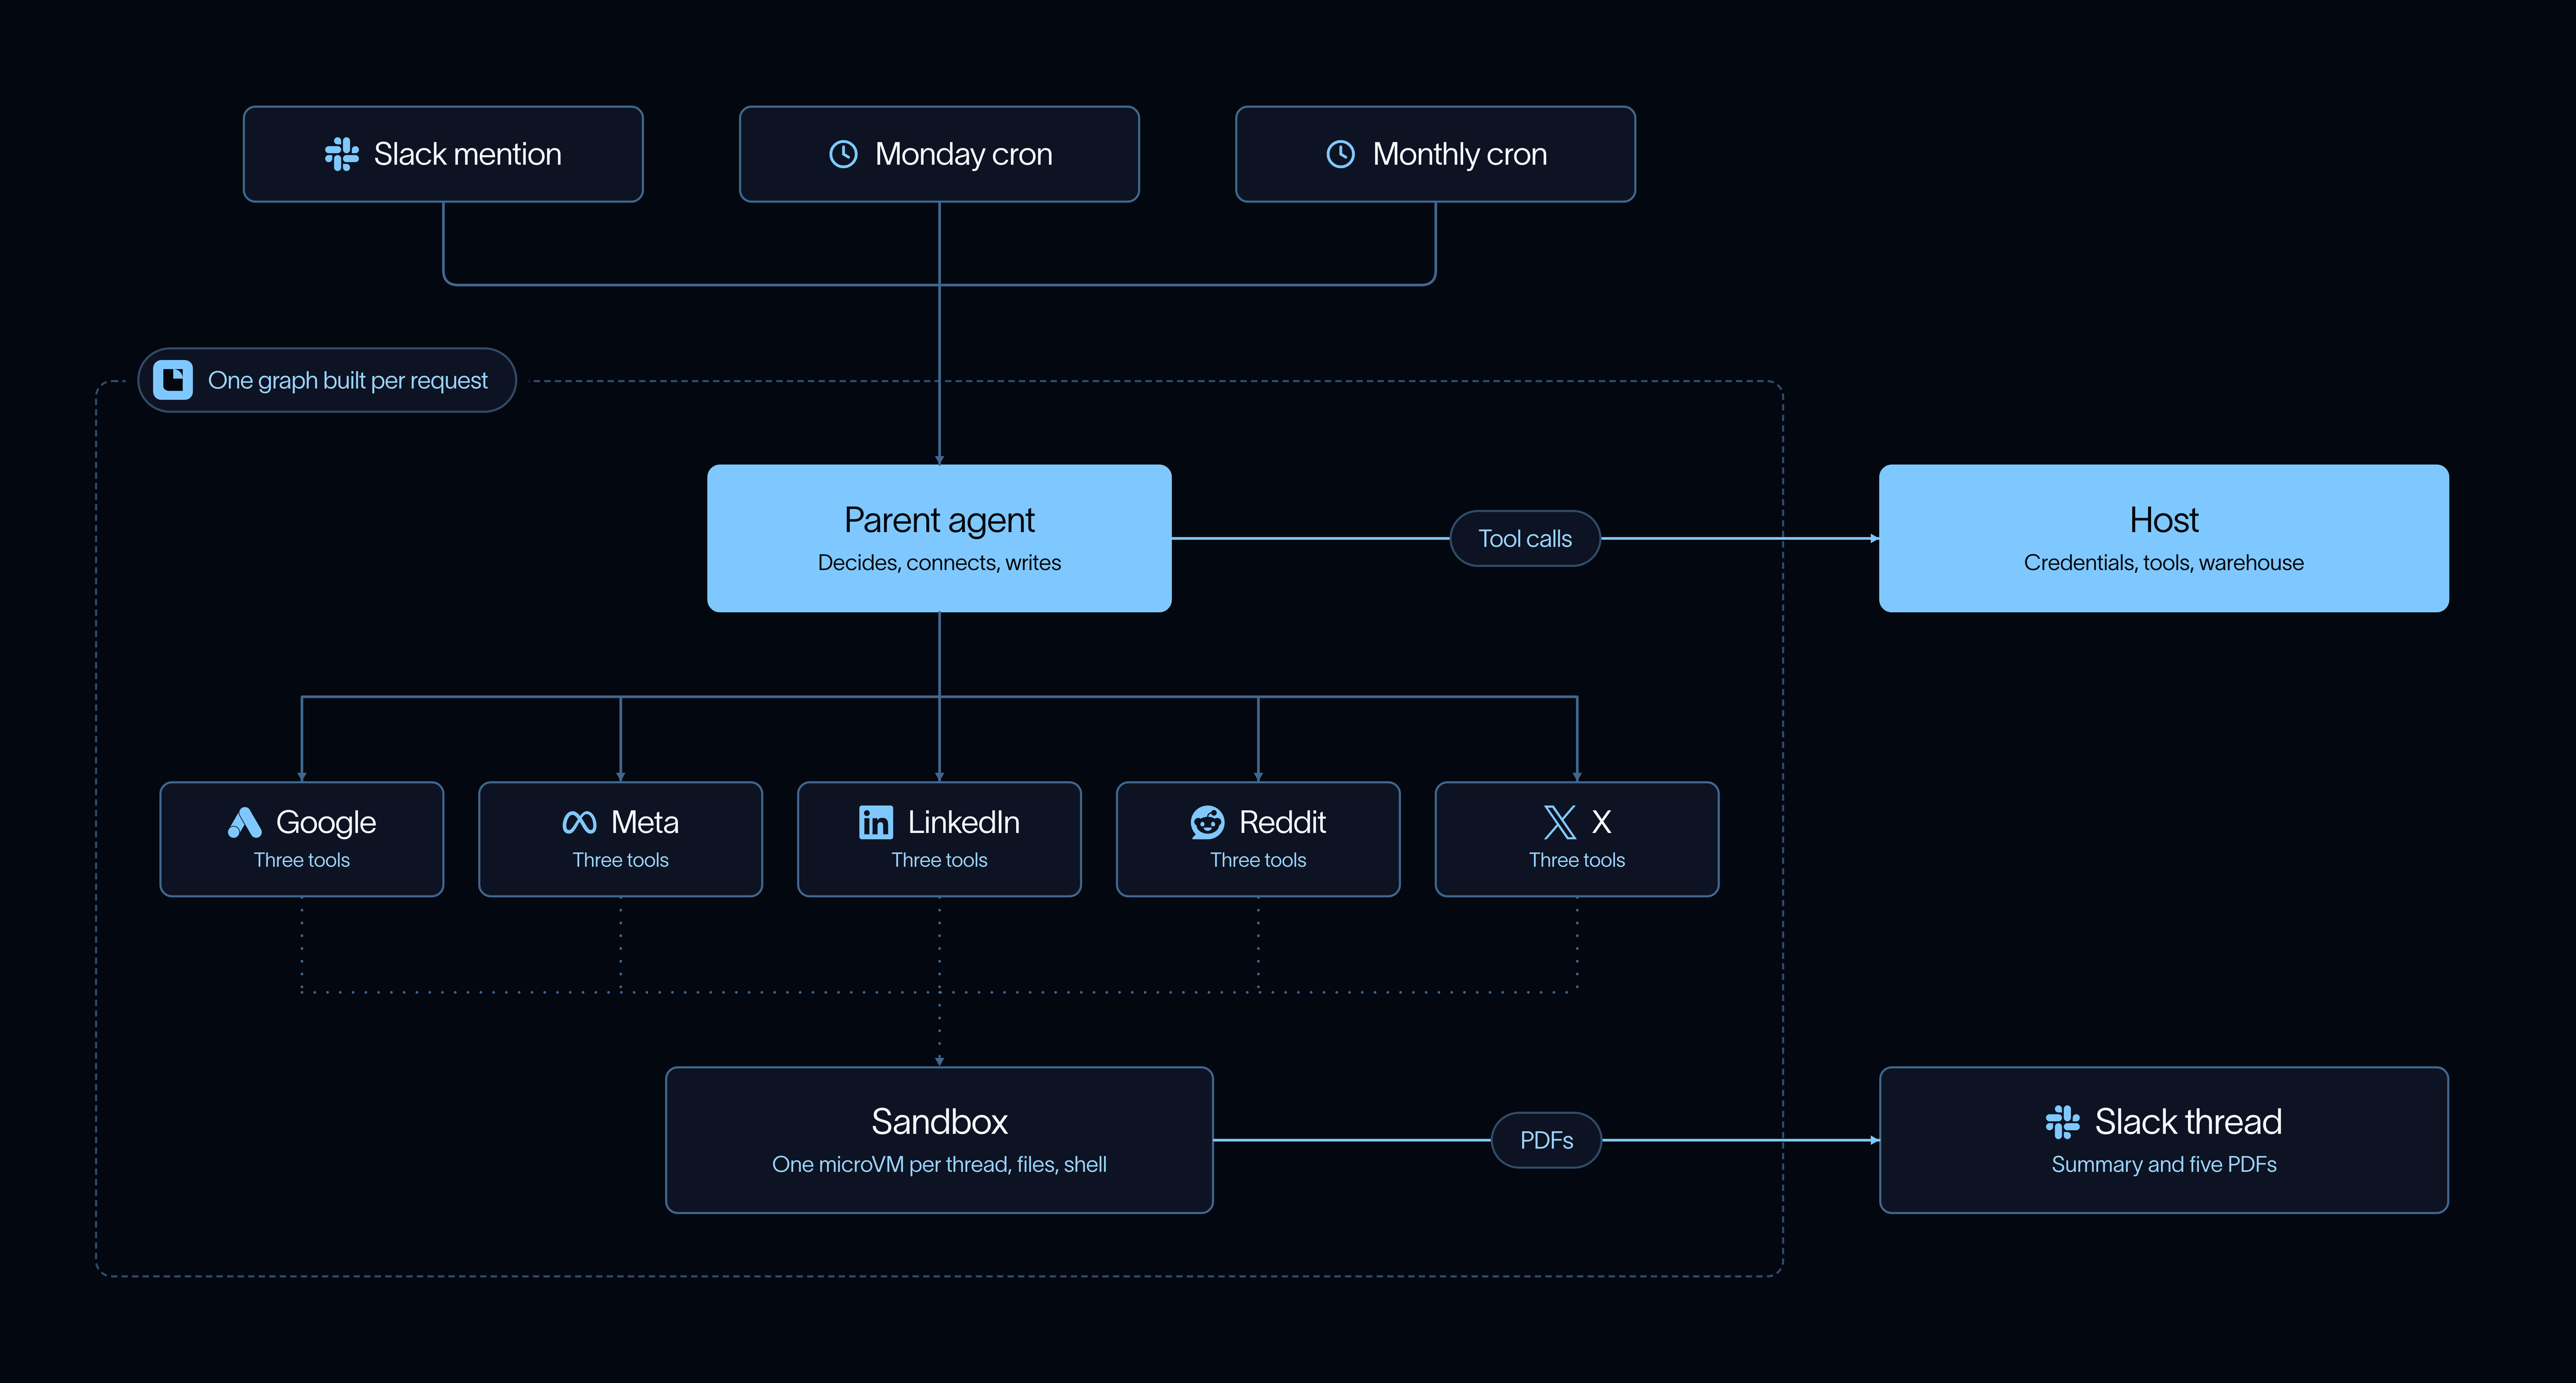
The company now describes that as a mistake: it was treating the two agents as two products when they are two entry points into the same analysis. The fix was one graph instantiated fresh for every request, with Slack mentions and the Monday cron entering with different run modes. Scheduled runs see a single tool, task(), which delegates to one subagent per platform. Slack gets a broader set of read, warehouse, and campaign-operations tools.
The unified agent is hosted on LangSmith Deployment, which handles hosting, scaling, and scheduled runs. Slack now shares the same sandboxed architecture, so the agent can open the report PDF and answer follow-up questions in the thread. A question like "What pipeline did we get for our ad spend?" can now be answered against the same analysis that produced the Monday report.
The First Version Cost Just Over $3 a Report and Took 1,112 Seconds
The first version of the weekly analysis loaded every campaign row, keyword, pipeline record, and landing-page check into context. The model calculated spend, worked out week-over-week changes, classified performance, and wrote the report.
On a frozen test set, a single report processed about 3.9 million input tokens, took 1,112 seconds, and cost just over $3. LangChain presents those numbers as a baseline, not a boast.
The current version moves the deterministic work into Python. Python fetches data, aligns date windows, calculates totals and comparisons, applies fixed rules, and writes compact results to the sandbox. The model focuses on judgment. The company's stated principle is to use models for judgment and code for consistency, because calculations, source-of-truth rules, and safeguards are better handled in code, which makes the agent faster, cheaper, and more reliable.
Stay ahead of the AI curve
The most important updates, news, and content — delivered weekly.
No spam. Unsubscribe anytime.
An earlier reporting workflow shows the same pattern at a smaller scale. After moving calculations to code, that workflow became about 40x cheaper and 13x faster, with runtime dropping from 18 minutes to 85 seconds.
The agent works across six platforms with different IDs, conversion definitions, attribution windows, and campaign hierarchies. LangChain's rule for handling that is to define an authoritative source per metric rather than wait for one perfect data model.
Ad platforms are the source of truth for media activity: spend, impressions, and clicks. The warehouse, BigQuery, is the source of truth for downstream outcomes: leads, opportunities, and pipeline. Salesforce is the source of opportunities and pipeline data in the warehouse. The warehouse is what connects campaign activity and website conversions to leads, opportunities, and pipeline.
Two examples show why the distinction matters. Google video campaigns did not map cleanly into the warehouse because the warehouse joined on keywords, and video campaigns do not always have keywords. About 10% of Google spend was missing from the warehouse as a result. Separately, Meta could tell that an ad generated a conversion, but the warehouse better identified the conversion type, for example "Contact Sales" versus "Sign Up."
Source-of-truth rules are encoded in the wiki, and tools that would query the wrong system are removed so the agent cannot go looking in the wrong place. When data cannot be joined reliably, the agent preserves the limitation and includes the source, date window, and attribution model in its answers. The post's guidance is not to wait for one perfect data model before an agent can work across systems: define the authoritative source per metric, make the rules explicit, and preserve uncertainty.
Tool sprawl was the next problem. Pipeboard, which provides an MCP catalog exposing ad-platform tools, exposes more than 200 ad-platform tools through its MCP. In June, a smaller read-only catalog required 38,000 tokens just to load tool names, descriptions, and arguments. The warehouse had its own version of the problem: fixed queries covered recurring questions, and each new grouping required another dedicated tool.
LangChain's answer was to give the agent a small interface instead of a large catalog. For the Pipeboard catalog, three tools: Search finds up to eight tools, Read loads the full schema for a selected tool, and Run executes the tool through the server. Campaign writes use a separate approval-gated path. For the warehouse, two flexible tools: Describe available tables and fields, and Run an analytical query.
The catalog brought the first turn down to about 12,000 tokens, which the company says is 4x cheaper than loading every schema while maintaining the same judged quality. The catalog has nearly tripled since then, while context cost stayed roughly consistent.
The team did not assume the query interface was strictly better. It tested fixed warehouse tools, the query interface, and both together across 60 live runs. Fixed tools worked well for routine questions but reported deeper questions as unsupported. Both versions with the query interface answered all analytical questions. LangChain kept both approaches: fixed tools for the fast path, the query interface for unanticipated questions.
The general lesson in the post is to give the agent a way to find and query capabilities on demand instead of putting every tool into context upfront.
Multi-platform analysis raised an architecture question. LangChain tested three options: one isolated run per platform, one agent handling every platform, and a parent agent delegating to one subagent per platform.
Separate runs performed worst. They produced multiple Slack messages and struggled to synthesize cross-channel performance. Both consolidated approaches produced a single output with cross-platform synthesis. LangChain chose the parent-plus-subagents architecture to keep the parent context small and give each platform its own context window.
That choice surfaced two isolation bugs. In the first, two subagents wrote reports to the same location and shared a "done" flag. The first subagent finished, and the second mistook the shared state and stopped without producing a report. The fix was to give each platform its own report location and completion state.
In the second, a subagent got stuck verifying its own work, kept checking files, burned tokens, and tried to build a PDF from scratch. Subagents now get only three tools: read context, compute, and render. If render succeeds, the job is done.
The post's conclusion is that separate context windows do not automatically give full isolation. Isolation has to be designed explicitly.
The agent can propose changes in Slack: adding a keyword, updating geographic targeting, or creating a new search campaign. It can also propose new keywords, targeting changes, ad copy, or new search campaigns based on its playbook and encoded judgement.
Permissions are enforced at the server. Teams outside paid media can ask questions, but only designated team members can edit or approve campaign changes. The server checks Slack user IDs, and unauthorized requests are blocked while the proposal remains pending.
Proposed changes appear in a Slack approval card built with Block Kit. Authorized reviewers can compare current and proposed values, make edits, and approve the final plan. Code then applies the approved change and checks the ad platform to confirm success.
LangChain's stated lesson is that closing the loop requires more than write access. The agent needs a clear action path with permissions, approvals, and verification.
Slack worked well for focused decisions, and it remains the primary interface for the agent: weekly reports are posted there, follow-up questions are asked there, and approval cards for campaign changes appear there.
But as the agent handled more complex work, including many ad groups, creatives, bulk edits, and multiple revision rounds, Slack became harder as a primary workspace. LangChain is moving complex workflows to a dedicated interface built around the agent, while keeping Slack for lightweight questions, review, and approvals. The guidance in the post is that Slack works best for relatively focused decisions, and complex workflows need a dedicated interface.
Design Principles for the Next Build
The post closes with a set of design principles for the next build, several of which are stated as corrections to earlier assumptions.
The company also states its overall posture plainly: treat agents like knowledge workers, and expect the strongest results to come from a well-designed workspace with a sandbox, software, business context, and clear operating instructions. Design agents around the full workflow, the post argues, because the agent needed to find tools, work within permissions, and move from analysis to action.
The post frames the goal in terms of capability rather than cost. "We wanted an agent that could handle questions we hadn't anticipated, produce verifiable numbers, and act on findings," the authors write.
LangChain says the agent will become more proactive by continuously monitoring campaign performance, surfacing changes, and proposing new experiments.
The bigger opportunity, according to the post, is to connect learnings across GTM. Campaign engagement informs sales follow-up. Pipeline progression, sales conversations, and deal outcomes improve the company's understanding of its ideal customer and influence the next campaign. Over time, LangChain wants GTM agents to contribute to the same shared knowledge and playbooks so that learnings improve targeting, messaging, and experimentation across the funnel.
The company is also running a webinar, "GTM Engineering Live: How We Built Our Paid Media Agent," on September 23 at 11am Pacific, to demo the agent and walk through the code.
The open-source release includes ad-platform tools, paid media skills, a sample wiki, reporting, and approval workflows. LangChain's call to action for teams that want to try the underlying platform is to try LangSmith or get a demo.