LangChain has open-sourced its Paid Media Agent and published a technical deep-dive on how it was built, covering architecture, context design, tool discovery, isolation, and approval workflows. The post, published September 13, 2026 and running 19 minutes, was written by Amal Irgashev, Danny Lambert, and Jan Gomez. It walks through a system that runs every Monday, combines ad-platform data with lead and pipeline data from the warehouse, and posts a summary and branded PDF per platform in Slack.
The release includes ad-platform tools, paid media skills, a sample wiki, reporting, and approval workflows. Teams can deploy it to Slack in one command with Managed Deep Agents.
The agent exists because LangChain's own marketing team had a problem. The company's sales pipeline grew organically for its first three years through open source, content, YouTube, community, and meetups. In January, LangChain launched paid advertising to reach new regions and enterprise decision makers. The goal was to scale from organic to five paid channels in six months. The small marketing team then had to track campaigns across channels, creative and targeting experiments, and performance data, while each ad platform kept its own data schema and campaign parameters did not map cleanly to outcomes like sales inquiries, signups, and content downloads. Product release cadence accelerated, increasing campaign volume.
The results came in. Paid media went from 0 to 20% of marketing pipeline in six months. Cost per qualified lead fell 30% from June to August, while monthly spend rose about 60% over the same period. LinkedIn, the largest social channel, saw CPL 40% lower than January. LangChain says it saved about $5K per month by bringing analysis and reporting in-house instead of using an agency.
The blog post frames the central question the agent answers: "What pipeline did we get for our ad spend?"
One Graph, Two Entry Points
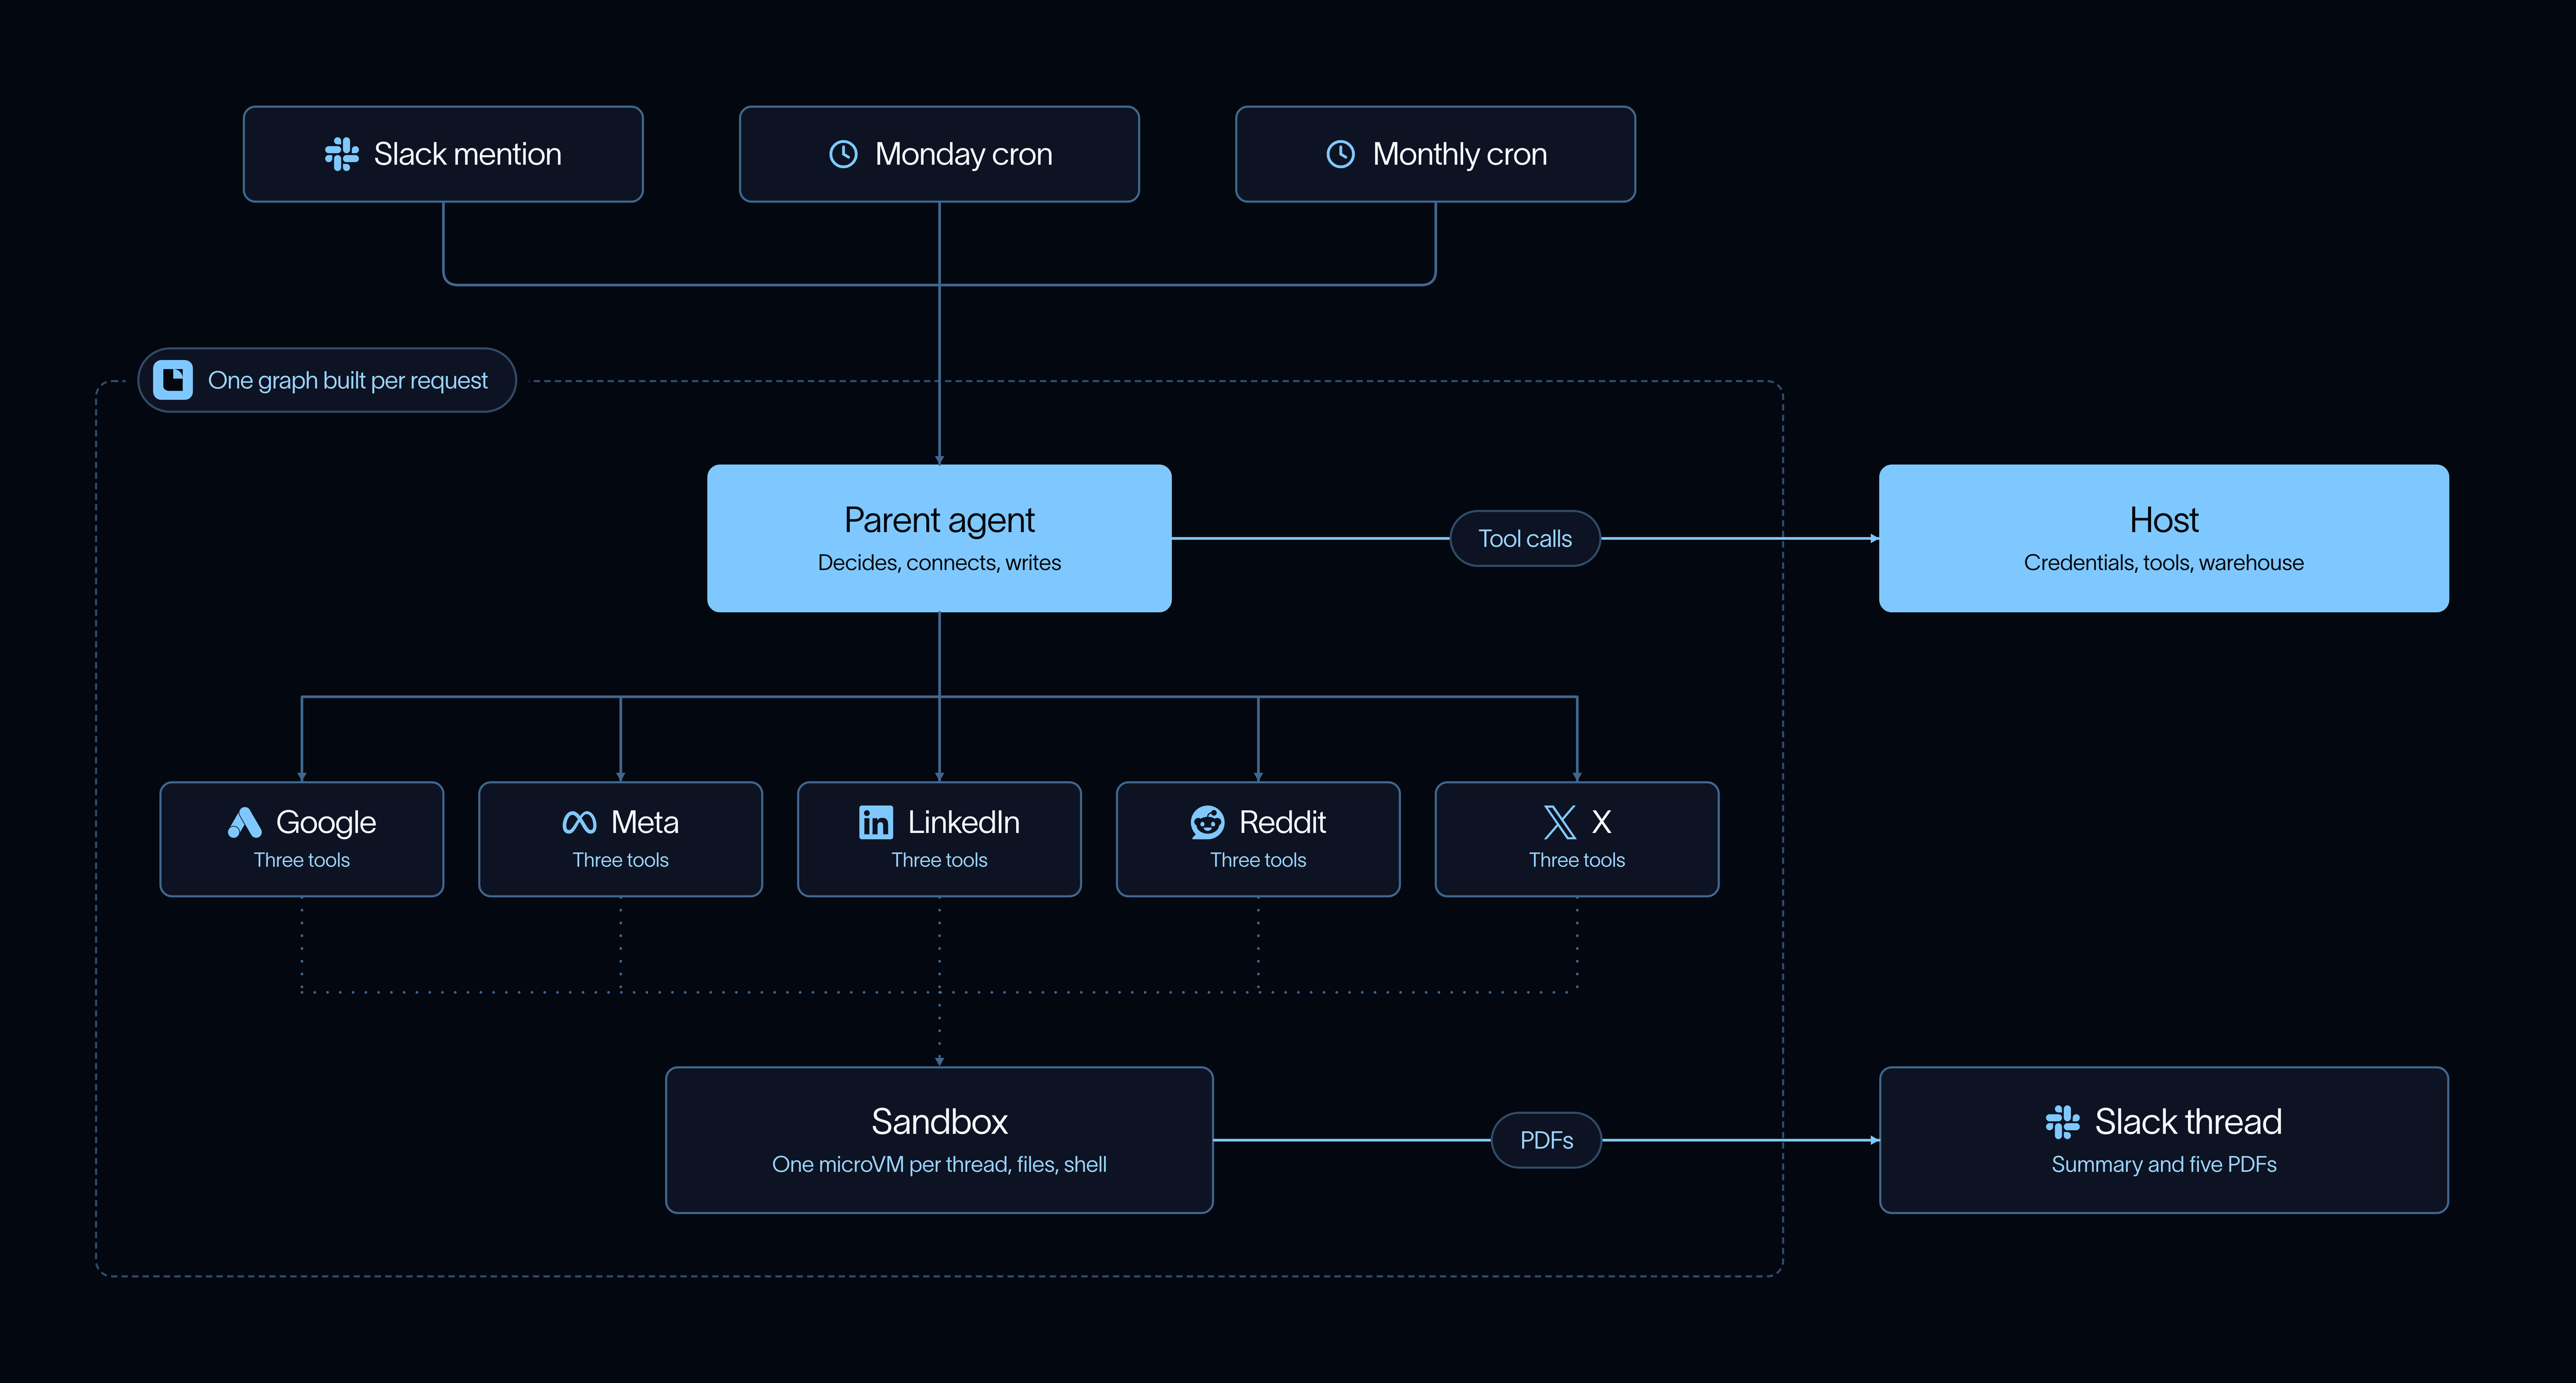
The agent lives in Slack and runs every Monday. It combines ad-platform data with lead and pipeline data from the warehouse, then posts a summary and a branded PDF per platform. The team can tag the agent in a thread for follow-up questions. It can also propose new keywords, targeting changes, ad copy, and new search campaigns.
The build rests on a stated principle: a coding agent is a knowledge worker. LangChain used its own Deep Agents as the agent harness rather than building from scratch. Deep Agents manages access to files, code execution, and working memory, and gives the model tools to plan, delegate to subagents, and manage context. Managed Deep Agents handles hosting, sandboxes, Slack integration, and schedules, an abstraction that lets teams focus on tools, context, and decision rules.
Every run gets a LangSmith Sandbox, an isolated microVM with a 32 GB disk and a shell. The sandbox is equipped with pandas, DuckDB, openpyxl, WeasyPrint, and Jinja2. Business knowledge is stored in Markdown across six skills and a nineteen-page wiki. LangChain baked the software and the wiki into a snapshot, reducing average startup time by 10 seconds. The post notes that different agents need different computers: a content generation agent's sandbox might have a headless browser, ffmpeg, media tools, and a brand book, while a finance agent might need openpyxl and DuckDB.
Context is split into five layers: system prompt, skills, wiki, live tools, and deterministic code. The layers are ordered by how quickly they change. The system prompt is a one-sentence role description plus three sections covering how to operate, where numbers come from, and how to present results. The rest are pointers. The authors describe the system prompt as a map that helps the agent find what it needs without carrying everything in context.
Skills are six folders of instructions, progressively disclosed. The agent initially sees only each skill's title and description. The wiki holds nineteen pages on the funnel, campaign intent, data source ownership, and past decisions, with July mentioned as an example of a past decision recorded there. Live tools cover 218 calls for spend, settings, and pipeline, fetched at request time because those values change daily. Deterministic code handles calculations, date windows, account matching, and hard safeguards. One example safeguard is a rule preventing the agent from cutting its top pipeline driver after one bad week, enforced in code rather than left to the model's judgment.
The skill versus wiki distinction is stated plainly: a skill should work at another company; the wiki should not. The wiki is company-specific. The post cites Karpathy's LLM wiki note and LangChain's Wiki Memory as the pattern behind this split.
The architecture was not the first attempt. LangChain originally built two agent graphs. The weekly report agent was scheduled, artifact-heavy, a Deep Agent with a sandbox, a large model, and PDF output. The Slack agent was a lightweight loop on a cheaper model with Google Ads and warehouse tools, no sandbox, and read-only access. The split lasted five weeks. Every new capability had to be implemented twice. Slack could not process attachments or answer follow-ups on Monday reports.
The authors call the mistake treating them as two products when they are two entry points into the same analysis. Now there is one graph, instantiated fresh per request. Scheduled runs see a single tool, task(), delegating to one subagent per platform. Slack gets a broader set of read, warehouse, and campaign-operations tools. The takeaway, in the post's words, is one runtime with a capability profile per entry point. Hosting, scaling, and scheduled runs are handled by LangSmith Deployment. Slack now shares the sandboxed architecture, so the agent can open the report PDF and answer follow-ups.
The First Version Cost Just Over $3 and Took 1,112 Seconds
The first version of the weekly analysis let the model do everything. It loaded every campaign row, keyword, pipeline record, and landing-page check into context. On a frozen test set, a single report processed about 3.9 million input tokens. It took 1,112 seconds and cost just over $3 per run.
Now Python fetches the data, aligns date windows, calculates totals and comparisons, applies fixed rules, and writes compact results to the sandbox. The model focuses on judgment: connecting evidence, explaining causes, evaluating campaigns, and recommending actions. The post's guidance is that the model should be used for judgment, not computation, and that code is better suited for deterministic work.
The earlier reporting workflow was optimized too. It became about 40x cheaper and 13x faster, with runtime dropping from 18 minutes to 85 seconds. The authors say calculations, source-of-truth rules, and safeguards are better handled in code, which makes the agent faster, cheaper, and more reliable.
Stay ahead of the AI curve
The most important updates, news, and content — delivered weekly.
No spam. Unsubscribe anytime.
The data problem is genuinely hard. There are six platforms with different IDs, conversion definitions, attribution windows, and campaign hierarchies. Ad platforms are the source of truth for media activity: spend, impressions, and clicks. The warehouse is the source of truth for downstream outcomes: leads, opportunities, and pipeline. BigQuery connects campaign activity and website conversions to leads, opportunities, and pipeline, while Salesforce is the source of opportunities.
Two mismatches illustrate the difficulty. For Google video campaigns, about 10% of Google spend was missing from the warehouse because the warehouse joined on keywords and video campaigns lack keywords. On Meta, the platform could report a conversion, but the warehouse better identified the conversion type, for example Contact Sales versus Sign Up. Source-of-truth rules are encoded in the wiki, and tools that query the wrong system were removed. When data cannot be joined reliably, the agent preserves the limitations and includes the source, date window, and attribution model. The post's advice is that you do not need one perfect data model before an agent can work across systems; you need to define the authoritative source per metric.
38,000 Tokens to 12,000, and a Catalog That Nearly Tripled
Tool discovery got its own treatment. Pipeboard, an MCP provider, exposes more than 200 ad-platform tools. In June, a smaller read-only catalog required 38,000 tokens just to load tool names, descriptions, and arguments. LangChain put the Pipeboard catalog behind three tools: Search, which finds up to eight tools; Read, which loads the full schema for a selected tool; and Run, which executes through the server. Campaign writes use a separate approval-gated path. The warehouse has two flexible tools: Describe tables and fields, and Run analytical query.
The catalog brought the first turn down to about 12,000 tokens. It was 4x cheaper than loading every schema while maintaining the same judged quality. The catalog has nearly tripled since then while context cost stayed roughly consistent. The principle is to give the agent a way to find and query capabilities on demand instead of loading every tool upfront.
The warehouse interface was tested rather than assumed. LangChain tried fixed warehouse tools, a query interface, and both together across 60 live runs. Fixed tools worked for routine questions but reported deeper questions as unsupported. Both versions with the query interface answered all analytical questions. The team kept both approaches: fixed tools for the fast path, the query interface for unanticipated questions.
Isolation Bugs and the Three-Tool Subagent
LangChain tested three architectures on live data: one isolated run per platform, one agent for all platforms, and a parent agent delegating to one subagent per platform. Separate runs performed worst. They produced multiple Slack messages and struggled to synthesize across channels. The team chose parent-plus-subagents, which keeps the parent context small and gives each platform its own context window.
Isolation brought two bugs worth documenting. In the first, two subagents wrote reports to the same location and shared a done flag. The first finished, the second mistook the state, and stopped without producing a report. The fix was giving each platform its own report location and completion state. In the second, a subagent got stuck verifying its own work, kept checking files, burned tokens, and tried to build a PDF from scratch. Subagents now get only three tools: read context, compute, and render. If render succeeds, the job is done.
The post's caution is that a separate context window is only one part of isolation. The rest is up to the designer. The authors also note that the context window is often the bottleneck, not the model, and that many apparent reasoning failures are context failures. A naive approach of putting all context in the system prompt would lead to an overly long, expensive, stale prompt. The strongest results came from giving the agent a well-designed workspace with a sandbox, software, business context, and clear operating instructions.
Approval Cards, Slack User IDs, and a Verified Write
Closing the loop requires more than write access. The agent can propose changes in Slack: add a keyword, update geographic targeting, create a new search campaign. Only designated team members can edit or approve campaign changes, and the server checks Slack user IDs. Unauthorized requests are blocked and the proposal remains pending. Proposed changes appear in an approval card built with Block Kit. Authorized reviewers can compare current and proposed values, make edits, and approve the final plan. Code then applies the approved change and checks the ad platform to confirm success. The post's summary of this requirement is that closing the loop needs permissions, approvals, and verification, not just write access.
Slack worked well for focused decisions. It was harder for complex work like many ad groups, bulk edits, and multi-round revisions. LangChain is moving complex workflows to a dedicated interface while Slack remains the place for lightweight questions, review, and approvals. The guidance is to match the interface to the work.
The agent was designed as a continuous learning loop: analyze performance, make a change, observe the outcome, capture the learning, and apply the insight. The goal was to make the marketing team more productive while continuously improving campaign performance. The post says the agent needed to find the right tools, work within clear permissions, and move from analysis to action.
What LangChain Says It Would Do Differently
Next on the roadmap: making the agent more proactive by continuously monitoring campaign performance, surfacing changes, and proposing experiments. The bigger opportunity the authors describe is connecting learnings across GTM so that campaign engagement informs sales follow-up and pipeline progression improves ideal customer understanding. Over time, LangChain wants GTM agents to contribute to the same shared knowledge and playbooks.
LangChain is hosting a webinar, GTM Engineering Live: How We Built Our Paid Media Agent, on September 23 at 11am Pacific.